AI Tools · AI Development

Pinecone

Vector database for building high-performance, scalable search and recommendation systems with AI.

Our take: Pinecone is the leading fully managed vector database for storing and querying high-dimensional embeddings at scale.

Best forPinecone is designed for developers, data scientists, and AI practitioners who need a high-performance, scalable solution for handling large-scale vector data
ReviewedPricing: Freemium
Try PineconeFree tier; paid from $20/mo (Builder)
The bottom line

The go-to managed vector DB for production AI apps — generous free tier, then scales cleanly from $20/mo.

Our score

Reviewed by the Conversion Gems editorial team. Hover a facet to focus it; click to pin.Tap a facet to focus it.

Community ratings

Shown for context only. Our score is independent.

G2
4.6 out of 5
30+ reviews

4.6 / 5 aggregate · across 1 source

Third-party ratings shown verbatim; aggregate weighted by review volume.

What it is, and why we rate it

One line each. Open a row for detail.

What it really isPinecone — fully managed serverless vector database for AI-powered search and retrieval.
Our takePinecone is the leading fully managed vector database for storing and querying high-dimensional embeddings at scale.
Pinecone now has a permanent free Starter tier, and pricing uses a read/write-unit model with flat-rate Builder ($20/mo) and usage-based Standard ($50/mo floor) plans. It is purpose-built for RAG pipelines, semantic search, recommendation engines, and anomaly detection, with real-time indexing and sub-millisecond query latency as core selling points.
Why we rate itPinecone pioneered the managed vector-DB category and still leads on developer experience — one-line SDK calls, serverless scaling, and integrations with every major LLM framework.
The 2025–2026 shift to unit-based pricing makes costs more predictable for growing teams.
The catchCosts can escalate sharply at high query volumes on Standard/Enterprise; per-unit pricing requires careful capacity planning.
Starter is AWS us-east-1 only, and the platform is entirely proprietary — no self-host option outside BYOC.

Best / not good for

Best for
  • RAG pipelines and LLM-powered semantic search at scale
  • Recommendation and personalization engines needing real-time vector retrieval
  • AI teams wanting zero-ops infrastructure for embedding storage
Not good for
  • Pure relational or structured-data workloads with no embedding use case
  • Cost-sensitive projects at very high query volumes (open-source Weaviate/Qdrant may be cheaper)
  • Teams requiring fully self-hosted or on-prem vector storage
Trade-offs

Friction report

Trade-offs to know before signing up.

  1. Time to value
    Fast: SDK install, create index, and upsert vectors in under 15 minutes; Starter tier requires no credit card.
  2. Scale breakpoint
    Standard's per-unit pricing becomes expensive beyond ~50M read units/month; dedicated read nodes help but add cost.
  3. Walled garden
    High: proprietary managed service with no open-source core; data portability requires manual export and re-ingestion into another vector DB.

A look inside
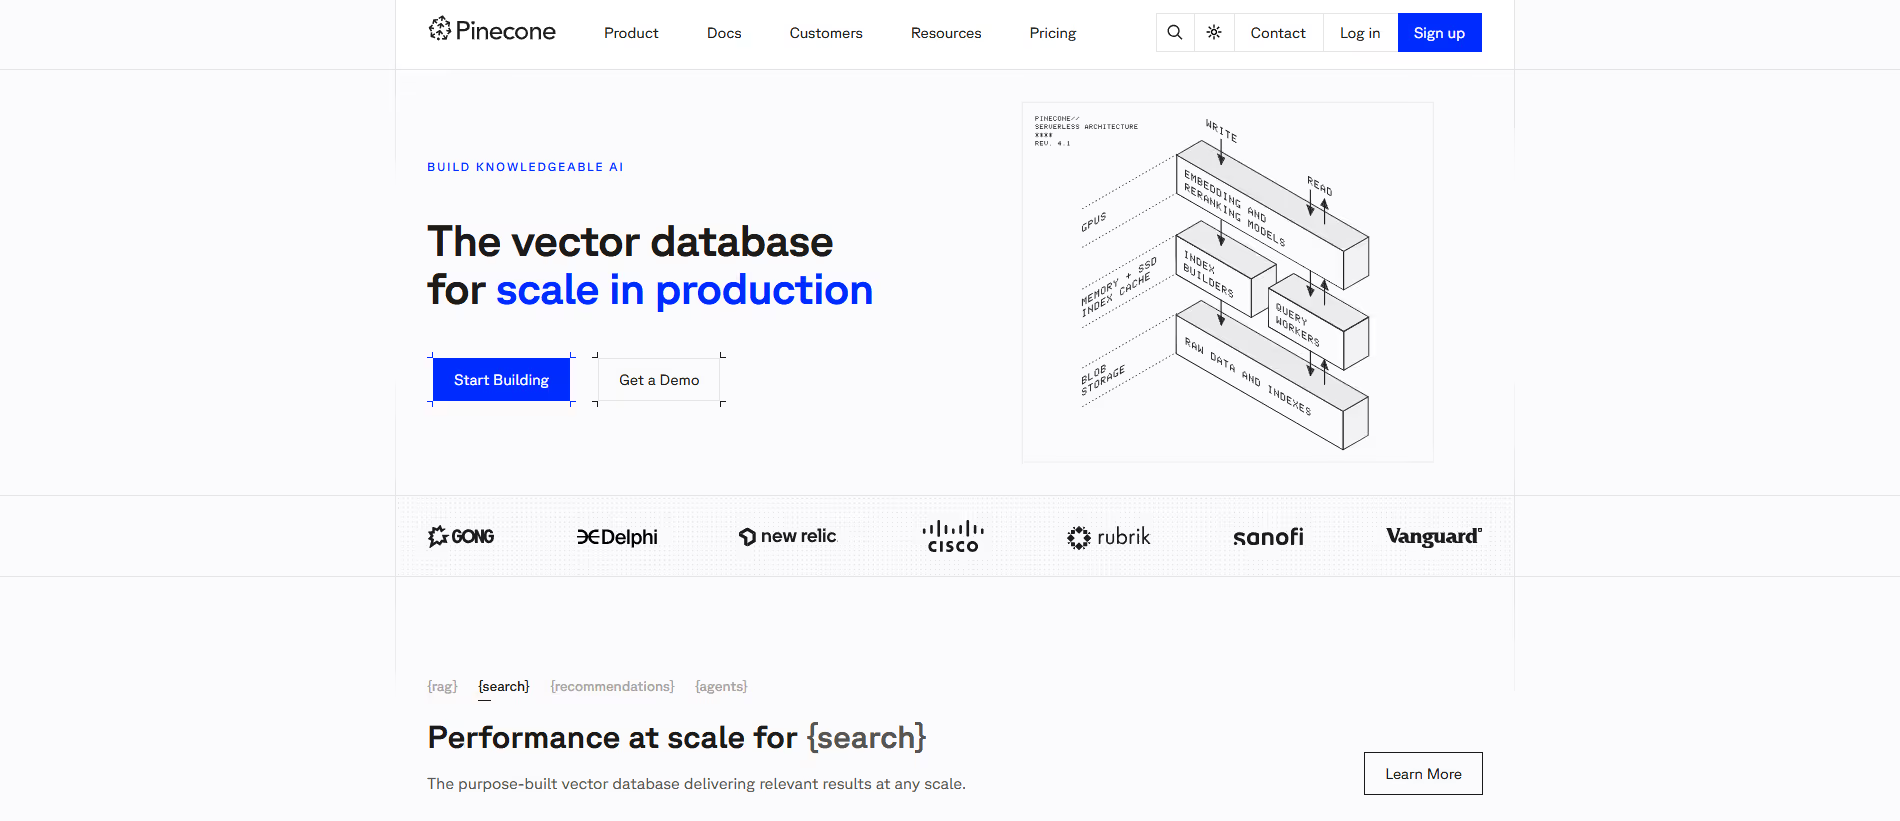
Pinecone product screenshot

Frequently Asked Questions

What is Pinecone and what does it do?

Pinecone is a vector database and similarity search platform purpose-built for AI applications that need to handle large volumes of unstructured data like text, images, or embeddings. Instead of storing traditional rows and columns, Pinecone stores vector representations generated by AI models, allowing developers to build applications that find semantically similar items, perform recommendation tasks, and power retrieval-augmented generation (RAG) workflows faster and more efficiently than using a regular database.

How does Pinecone help with AI search and retrieval?

When modern AI models convert content like text or images into numerical vectors, those vectors capture semantic meaning beyond keywords. Pinecone lets developers index and query those vectors with high performance, returning content that is most “similar” in meaning, not just keyword matches. This makes it ideal for tasks like retrieving relevant documents for a chatbot, finding similar product descriptions, or clustering customer feedback — all at production scale.

What features does Pinecone offer for developers and teams?

Pinecone provides a hosted vector database with features such as scalable indexing and querying, low latency retrieval, automatic replication and fault tolerance, and namespace isolation for multi-tenant apps. It supports multiple distance metrics (like cosine, dot product, Euclidean), hybrid search with metadata filtering, and seamless integrations with popular embedding model providers (e.g., OpenAI, Cohere, Hugging Face), making it easy to plug into your AI stack.

Can Pinecone be used in production environments?

Yes — Pinecone is built for production use with enterprise-grade performance, including horizontal scaling, access control, and service level agreements (SLAs). Teams can start with smaller deployments during development and scale up without major changes to application logic as data size and query demand grow. This reliability and manageability make Pinecone suitable for startups and large enterprises alike.

Who should use Pinecone and what benefits can they expect?

Pinecone is ideal for AI developers, data teams, ML engineers, and product teams building applications that rely on fast semantic search, recommendations, or contextual retrieval. Users can expect dramatically better search relevance, faster response times than traditional databases, and easier implementation of RAG, personalization, and recommendation systems without the heavy lifting of building and managing vector infrastructure from scratch.

Alternatives

Conversion Gems independently reviews every tool.

Tags

#VectorDB#Embeddings#AIInfra